IBM

The Accelerator Landscape

Ce cours n'est pas disponible en Français (France)

Nous sommes actuellement en train de le traduire dans plus de langues.
IBM

The Accelerator Landscape

Kaoutar El Maghraoui

Instructeur : Kaoutar El Maghraoui

Inclus avec Coursera PlusEn savoir plus

Obtenez un aperçu d'un sujet et apprenez les principes fondamentaux.
niveau Intermédiaire

Expérience recommandée

3 heures à compléter
Planning flexible
Apprenez à votre propre rythme
Obtenez un aperçu d'un sujet et apprenez les principes fondamentaux.
niveau Intermédiaire

Expérience recommandée

3 heures à compléter
Planning flexible
Apprenez à votre propre rythme

Ce que vous apprendrez

  • ·Explain why AI workloads benefit from domain-specific accelerators using Amdahl's law and arithmetic intensity.

  • ·Compare execution and memory models across GPU, TPU, Cerebras, Groq, and IBM Spyre.

  • ·Use a roofline model to distinguish compute-bound from memory-bound workloads.

Compétences que vous acquerrez

  • Catégorie : Artificial Neural Networks
  • Catégorie : Dataflow
  • Catégorie : Performance Testing
  • Catégorie : Large Language Modeling
  • Catégorie : Hardware Architecture
  • Catégorie : Computer Architecture

Détails à connaître

Certificat partageable

Ajouter à votre profil LinkedIn

Récemment mis à jour !

octobre 2026

Évaluations

2 devoirs

Enseigné en Anglais

Découvrez comment les employés des entreprises prestigieuses maîtrisent des compétences recherchées

 logos de Petrobras, TATA, Danone, Capgemini, P&G et L'Oreal

Élaborez votre expertise du sujet

Ce cours fait partie de la Spécialisation "Dataflow Architectures for AI"
Lorsque vous vous inscrivez à ce cours, vous êtes également inscrit(e) à cette Spécialisation.
  • Apprenez de nouveaux concepts auprès d'experts du secteur
  • Acquérez une compréhension de base d'un sujet ou d'un outil
  • Développez des compétences professionnelles avec des projets pratiques
  • Obtenez un certificat professionnel partageable

Il y a 7 modules dans ce cours

This module introduces the course structure and the instructor. The course compares five accelerator architectures: NVIDIA GPUs, Google TPUs, the Cerebras Wafer-Scale Engine, the Groq LPU, and IBM Spyre. Each uses a different execution model to run the same PyTorch models. Each week examines one layer of the hardware and software stack and ends with a hands-on lab in Google Colab. Students also begin the Accelerator Landscape Map, a comparison table that is extended each week.

Inclus

1 vidéo

Since the end of Dennard scaling, single-thread processor performance has improved slowly, while the compute used to train AI models has doubled roughly every six months. This module covers the move from general-purpose processors to domain-specific hardware. It introduces Amdahl's law as a limit on acceleration, describes the properties that many AI workloads share, and defines arithmetic intensity. It then presents the roofline model, which uses arithmetic intensity to determine whether a workload is limited by compute or by memory bandwidth. The module closes by introducing the five accelerators used throughout the course.

Inclus

1 vidéo

Processors differ in when and where the next operation is selected. CPUs and GPUs select operations at runtime from an instruction stream. Many AI accelerators perform part or all of this scheduling in the compiler. This module compares instruction-driven, compiler-scheduled, and data-triggered execution. It describes the operation of a systolic array cycle by cycle and its implementation in the TPU matrix unit. The module concludes with a transformer block expressed as a dataflow graph and a comparison of the workloads suited to each execution model.

Inclus

1 vidéo

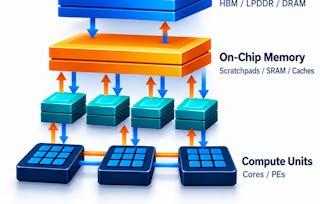
For many AI workloads, memory bandwidth and data placement limit performance more than peak compute. This module presents the memory hierarchy with measured figures from an NVIDIA H100 and traces the movement of one tensor through it. It compares hardware-managed caches with software-managed scratchpads and surveys the memory organization of all five accelerators, including the internal structure of an IBM Spyre chip. The module closes with the two phases of LLM inference, prefill and decode, and quantifies the weight traffic per generated token during small-batch decode.

Inclus

1 vidéo

Accelerator programming models range from kernel languages, which expose direct control of the hardware, to graph compilers, which provide portability across targets. This module positions CUDA, Triton, torch.compile, FX, and XLA within that range and describes the compilation path from a PyTorch model to vendor kernels. It describes the native programming model of each of the five accelerators. It then covers numeric formats such as FP8 and the conditions under which reduced precision improves performance.

Inclus

1 vidéo

This lab profiles LLM inference with Qwen 2.5 0.5B Instruct on a CPU and a GPU in Google Colab. Students build a benchmarking harness, identify the operators with the highest GPU time using PyTorch Profiler, and place the workload on a roofline for the assigned GPU. The lab concludes with the first row of the Accelerator Landscape Map. An optional Dataflow Deep Dive repeats the lab on IBM Spyre hardware for students in partnered programs.

Inclus

1 devoir1 laboratoire non noté

This quiz covers all four modules of the course: why AI needs specialized hardware, control-flow and dataflow execution, memory hierarchies, and the path from a PyTorch model to an accelerator. It has 16 questions, including calculations with Amdahl's law, arithmetic intensity and the roofline model. Allow about 40 minutes and keep a calculator nearby. You need 80% to pass, and you can take the quiz up to 3 times. Your highest score counts.

Inclus

1 devoir

Obtenez un certificat professionnel

Ajoutez ce titre à votre profil LinkedIn, à votre curriculum vitae ou à votre CV. Partagez-le sur les médias sociaux et dans votre évaluation des performances.

Instructeur

Kaoutar El Maghraoui
6 Cours73 apprenants

Offert par

IBM

Pour quelles raisons les étudiants sur Coursera nous choisissent-ils pour leur carrière ?

Felipe M.

Étudiant(e) depuis 2018
’Pouvoir suivre des cours à mon rythme à été une expérience extraordinaire. Je peux apprendre chaque fois que mon emploi du temps me le permet et en fonction de mon humeur.’

Jennifer J.

Étudiant(e) depuis 2020
’J'ai directement appliqué les concepts et les compétences que j'ai appris de mes cours à un nouveau projet passionnant au travail.’

Larry W.

Étudiant(e) depuis 2021
’Lorsque j'ai besoin de cours sur des sujets que mon université ne propose pas, Coursera est l'un des meilleurs endroits où se rendre.’

Chaitanya A.

’Apprendre, ce n'est pas seulement s'améliorer dans son travail : c'est bien plus que cela. Coursera me permet d'apprendre sans limites.’

Qu’est-ce qui vous amène sur Coursera aujourd’hui ?

Foire Aux Questions